Start with the actual workflow
Routing requests, tagging engineering documents and selecting developer tools favour different models. Use the matched task results to shortlist candidates, then validate on your own examples and costs of mistakes.
Compare every tested model on the same inputs. See where accuracy is strongest, how quickly models respond, and how much GPU memory they use.
Unofficial, independent testing. Use as is, without warranty or vendor endorsement.
These are the highest observed local accuracy scores across all 31 local models, with Jev shown alongside. Exact ties are retained. Small differences do not establish a statistically reliable lead, and there is no single overall ranking.
| Use case / benchmark | Highest-scoring local model(s) | Local accuracy | Jev accuracy | Scored cases |
|---|---|---|---|---|
| English request routing | Decider 4B v2.1 | 88.3% | 86.5% | 2,948 |
| Norwegian request routing | Imajev 4B | 82.2% | 81.8% | 2,948 |
| Norwegian review sentiment | Kev 4B | 73.9% | 71.9% | 1,173 |
| News classification | Laya / Laya multilingual | 91.5% | 89.0% | 200 |
| Emotion classification | Julia 144M | 91.0% | 60.0% | 200 |
| Spam screening | Laya / Laya multilingual | 100.0% | 98.0% | 200 |
| Phishing screening | Laya / Laya multilingual | 100.0% | 89.5% | 200 |
| Public JevBench | Plumb 4B | 89.6% | 86.1% | 231 |
| Developer-tool selection | Kev 4B | 71.1% | 69.9% | 900 |
Routing uses public assistant-service categories as a proxy for a business inbox. Public training overlap is unknown. Spam and phishing are reported Laya training tasks; these scores do not demonstrate unseen-domain security performance. All failures and abstentions count against accuracy.
Choose a task, then sort by accuracy, median response time or added VRAM. Every model stays in the accuracy comparison even when controlled timing is unavailable. Model names identify the tested size or quantized variant where available.
Norwegian routing: 2,948 public Bokmål test inputs, covering 18 assistant-service categories. This measures a routing proxy, not production support-ticket accuracy.
32 models · sorted by accuracy · Norwegian request routing
| Model / tested variant | Deployment | Accuracy | Answered | Median ms | Added VRAM GiB | Timing coverage |
|---|---|---|---|---|---|---|
| Imajev 4B | Local | 82.2%2,424/2,948 correct | 2,813/2,948 | 87.5 | 9.49 | 57/60 timing calls answered; 0 calls with native truncation. |
| Decider 4B v2.1 | Local | 82.0%2,418/2,948 correct | 2,948/2,948 | 58.5 | 8.35 | 60/60 timing calls answered; 0 calls with native truncation. |
| Jev 1.13.0 API | Hosted API | 81.8%2,412/2,948 correct | 2,948/2,948 | 271.1 | Unknown | 60/60 timing calls answered; 0 calls with native truncation. |
| Wald 4B v1.2 | Local | 80.7%2,379/2,948 correct | 2,948/2,948 | 57.7 | 8.19 | 60/60 timing calls answered; 0 calls with native truncation. |
| Decision 2.0 Nox 4B | Local | 80.3%2,367/2,948 correct | 2,948/2,948 | 69.4 | 9.53 | 60/60 timing calls answered; 0 calls with native truncation. |
| Winnow 12B Q8 (Windows CUDA) | Local | 78.0%2,299/2,948 correct | 2,948/2,948 | Unavailable | Unavailable | No controlled measurement for this task. |
| Nev 2B Q8 | Local | 74.1%2,183/2,948 correct | 2,948/2,948 | 36.3 | 2.27 | 60/60 timing calls answered; 0 calls with native truncation. |
| Nimble 9B NF4 | Local | 74.0%2,181/2,948 correct | 2,948/2,948 | 171.4 | 8.33 | 60/60 timing calls answered; 0 calls with native truncation. |
| Plumb 4B | Local | 73.7%2,174/2,948 correct | 2,948/2,948 | 172.3 | 8.21 | 60/60 timing calls answered; 0 calls with native truncation. |
| Imajev 2B | Local | 73.1%2,156/2,948 correct | 2,911/2,948 | 70.3 | 4.64 | 60/60 timing calls answered; 0 calls with native truncation. |
| Decision 4B v1.2 | Local | 72.9%2,150/2,948 correct | 2,948/2,948 | 63.3 | 8.32 | 60/60 timing calls answered; 0 calls with native truncation. |
| Tev1 4B | Local | 72.7%2,143/2,948 correct | 2,948/2,948 | 77.9 | 8.24 | 60/60 timing calls answered; 0 calls with native truncation. |
| JevK5 4B | Local | 72.4%2,133/2,948 correct | 2,948/2,948 | 180.1 | 8.23 | 60/60 timing calls answered; 0 calls with native truncation. |
| Intern-Decision 4B | Local | 72.1%2,126/2,948 correct | 2,948/2,948 | 63.2 | 8.96 | 60/60 timing calls answered; 0 calls with native truncation. |
| Kev 4B | Local | 72.0%2,123/2,948 correct | 2,948/2,948 | 57.8 | 8.35 | 60/60 timing calls answered; 0 calls with native truncation. |
| Decider 2B | Local | 71.2%2,099/2,948 correct | 2,948/2,948 | 47.2 | 3.90 | 60/60 timing calls answered; 0 calls with native truncation. |
| Jev-Omni 12B NF4 (local variant) | Local | 69.7%2,055/2,948 correct | 2,948/2,948 | 139.9 | 7.70 | 60/60 timing calls answered; 0 calls with native truncation. |
| Decider 0.8B | Local | 68.6%2,021/2,948 correct | 2,948/2,948 | 47.1 | 1.83 | 60/60 timing calls answered; 0 calls with native truncation. |
| Cygnet 12B NF4 (local variant) | Local | 68.3%2,013/2,948 correct | 2,948/2,948 | 138.7 | 7.67 | 60/60 timing calls answered; 0 calls with native truncation. |
| Decision 2.0 Sol 2B | Local | 64.4%1,898/2,948 correct | 2,948/2,948 | Unavailable | Unavailable | No controlled measurement for this task. |
| Kev 0.8B | Local | 58.3%1,719/2,948 correct | 2,948/2,948 | 45.4 | 1.83 | 60/60 timing calls answered; 0 calls with native truncation. |
| JevK5 2B | Local | 57.1%1,682/2,948 correct | 2,948/2,948 | 128.0 | 3.87 | 60/60 timing calls answered; 0 calls with native truncation. |
| Decision 2.0 Kai 0.6B | Local | 54.7%1,614/2,948 correct | 2,948/2,948 | Unavailable | Unavailable | No controlled measurement for this task. |
| GLiNER Decide 340M | Local | 52.8%1,557/2,948 correct | 2,948/2,948 | 25.4 | 2.18 | 60/60 timing calls answered; 0 calls with native truncation. |
| Decision 2.0 Eos 0.8B | Local | 52.6%1,551/2,948 correct | 2,948/2,948 | Unavailable | Unavailable | No controlled measurement for this task. |
| Laya multilingual | Local | 51.3%1,511/2,948 correct | 2,948/2,948 | 22.8 | 1.79 | 60/60 timing calls answered; 0 calls with native truncation. |
| GLiNER Decide multilingual | Local | 49.4%1,455/2,948 correct | 2,948/2,948 | 14.1 | 1.45 | 60/60 timing calls answered; 0 calls with native truncation. |
| Julia 144M | Local | 39.8%1,174/2,948 correct | 2,948/2,948 | 13.6 | 0.95 | 60/60 timing calls answered; 0 calls with native truncation. |
| CLM 8B INT8 | Local | 30.3%894/2,948 correct | 2,948/2,948 | 227.1 | 8.47 | 60/60 timing calls answered; 0 calls with native truncation. |
| GLiNER Decide 1B | Local | 24.7%729/2,948 correct | 2,948/2,948 | 29.8 | 4.93 | 60/60 timing calls answered; 0 calls with native truncation. |
| Laya | Local | 21.1%621/2,948 correct | 2,948/2,948 | 26.4 | 2.75 | 60/60 timing calls answered; 0 calls with native truncation. |
| Von | Local | 13.4%394/2,948 correct | 2,948/2,948 | 18.8 | 2.04 | 60/60 timing calls answered; 0 calls with native truncation. |
Accuracy uses the full scored group under the original split rules. “Answered” includes correct and incorrect answers; its shortfall includes failures, native rejections and abstentions. Timing uses separate fixed samples, batch size one, three serial passes and excluded warm-ups. Medians cover answered calls; blocks with fewer than 90% answered calls are withheld. Counts and native truncation remain visible.
VRAM is the sampled whole-device peak above idle on an RTX 5070 Ti 16 GB, not the model file size or isolated process memory. Desktop activity can affect small differences. Jev response times include network transport; its server VRAM is unknown. Missing measurements are never estimated. CLM timing reuses precomputed candidate embeddings for the fixed workload.
The bubble plots use complete task groups and controlled measurements. They cover 29 configurations. Kai, Eos and Sol were outside this timing protocol; Eos and Sol have separate serving tests.
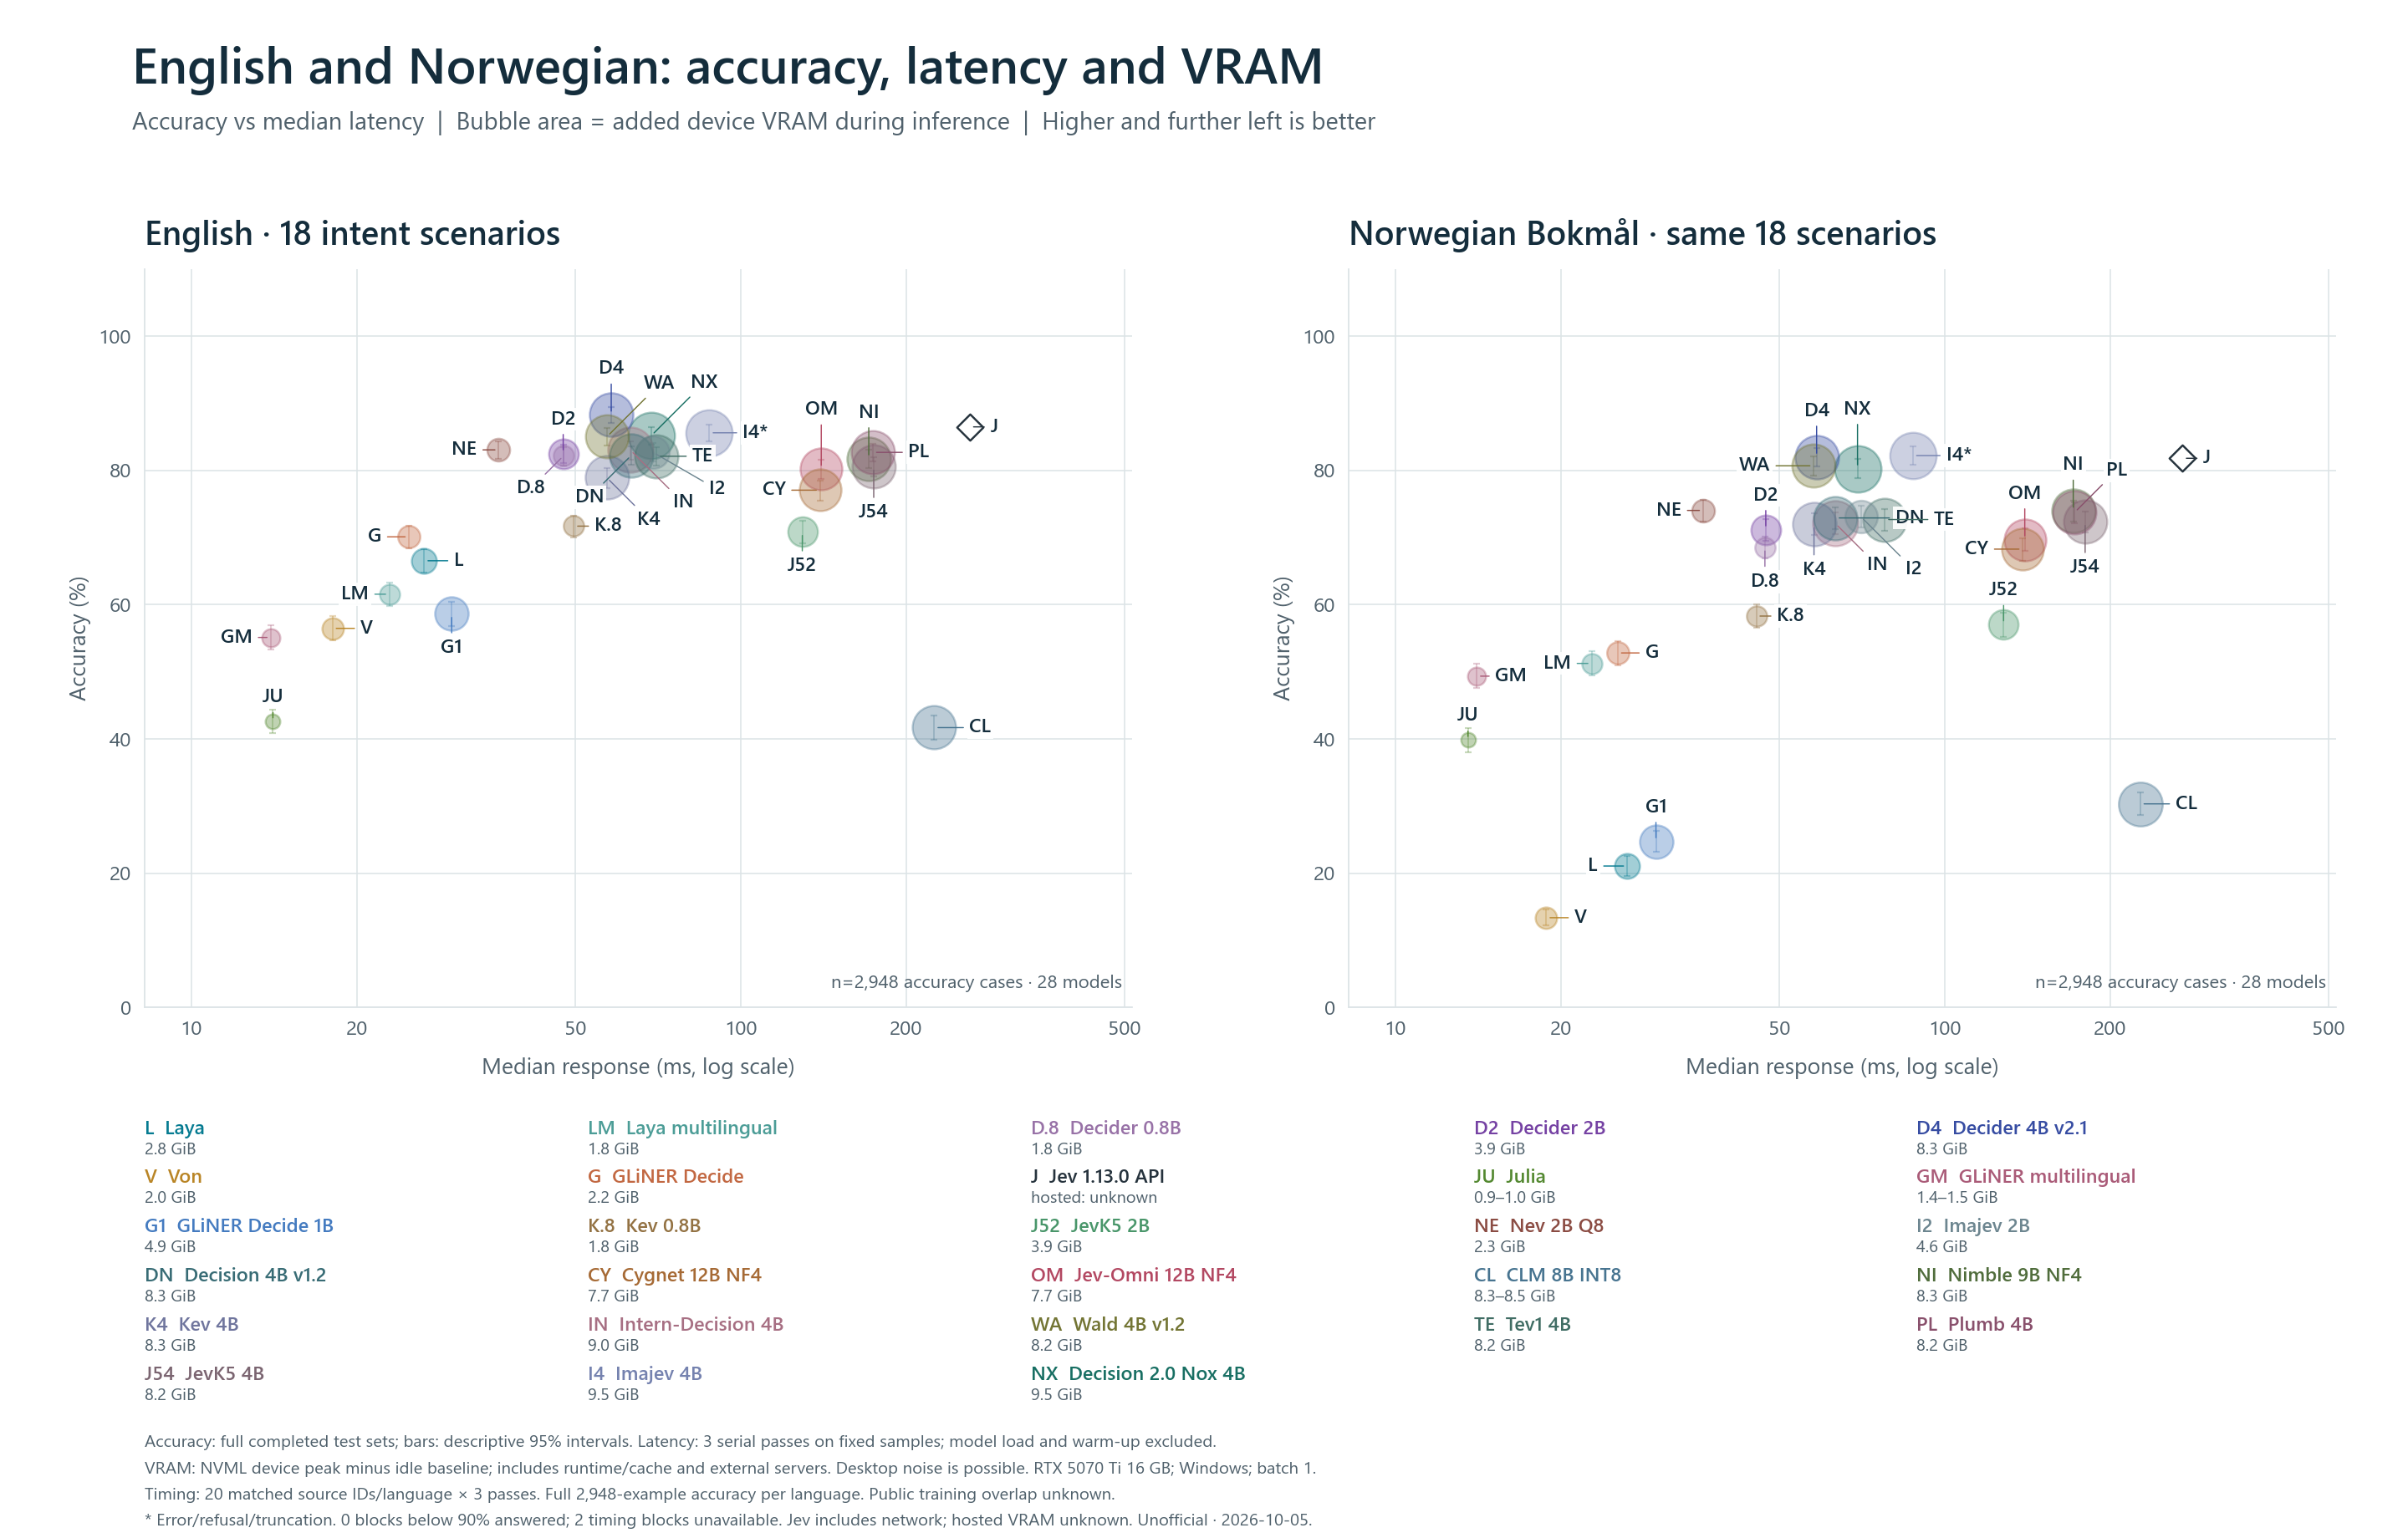
Explore all five graph sets · Download the publication graphics
Routing requests, tagging engineering documents and selecting developer tools favour different models. Use the matched task results to shortlist candidates, then validate on your own examples and costs of mistakes.
A supervised TF-IDF + linear SVM reached 89.1% on Norwegian routing using labelled training data. The decision models here had no task-specific fitting. If labels are available, include a trained classifier in the pilot.
Industrial routing and document examples are small authored diagnostics, not expert-validated industry benchmarks. These tests do not measure staff-time savings, production safety or return on investment.
All 17,576 cases per local model are accounted for. 235 runtime failures remain after repeated attempts; native rejections and abstentions are reported separately. Eight controlled timing groups are unavailable. The benchmark evidence is unchanged by this presentation revision.
Every scored task, all local models and the pinned Jev 1.13.0 reference, with confidence and coverage details.
All-model coverage, recorded failures and recovery evidence.
What was reproduced, where configurations differed and what could not be tested.
Frozen fixtures, original scoring, pinned revisions and the distinction between accuracy runs and controlled timings.